Rolling Out Conversation Training Across 12 Countries: Language, Culture and Compliance in One Programme
Multi-country training rollouts fail when scenarios are translated instead of localised. Keep the competency model and rubric global, rebuild personas, objections and regulatory scripts locally.
Roleplays Team
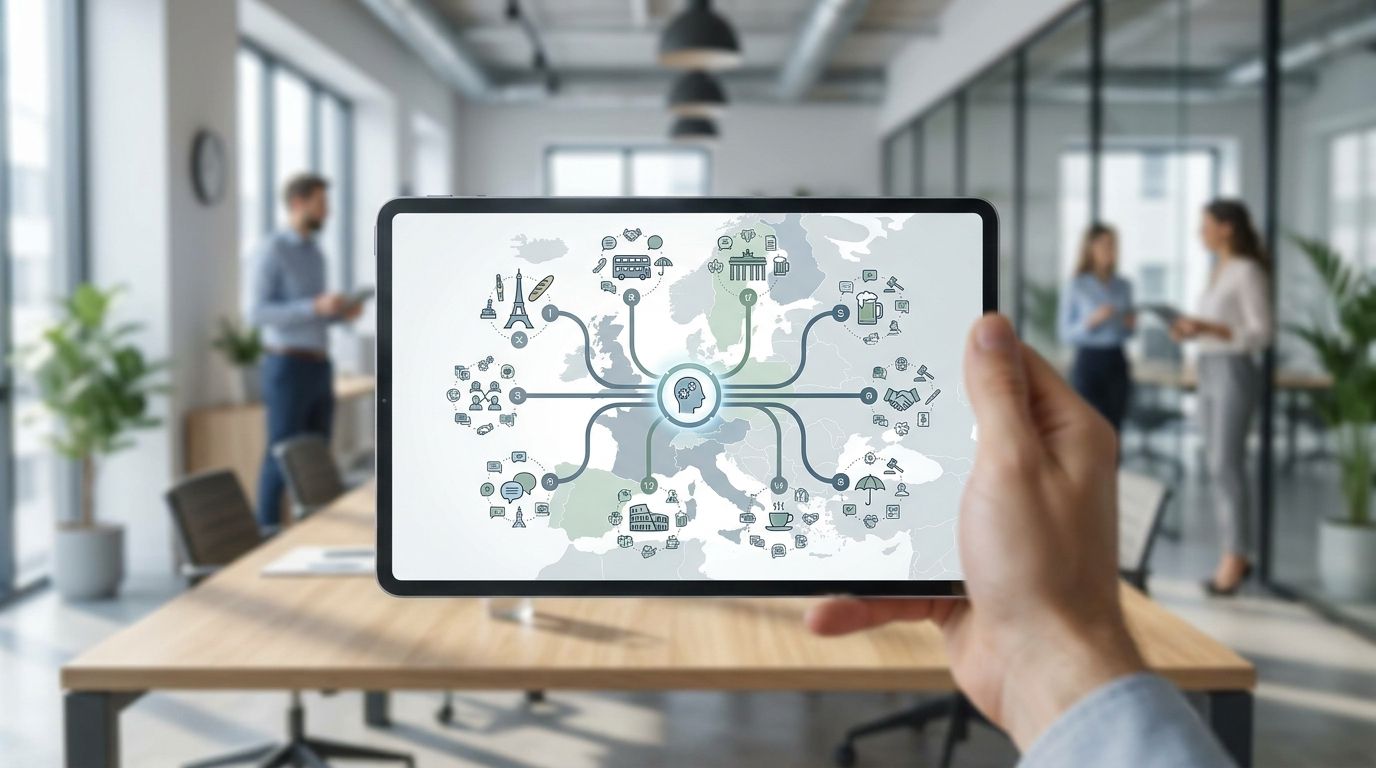
TL;DR One competency framework, twelve languages, twelve regulatory realities. What stays global is the rubric and the competency model. What goes local is scenarios, personas, objections and regulatory scripts. Translating scenarios is the single most common way a multi-country training deployment quietly fails, because objections are cultural, not linguistic.
You approved the programme in Q1. One competency model, one platform, one set of dashboards for the executive committee. By Q3 you have a German works council asking who scores what, a French team that says the discovery scenario “doesn’t sound like anything a real buyer would say”, a Polish country manager who translated everything himself over a weekend, and a Nordic team politely ignoring the whole thing.
None of that is a technology problem. It’s a design problem, and it starts with deciding what is genuinely global.
What stays global, what goes local
The rule we use is simple: the measurement stays global, the fiction goes local.
The competency model stays global. If “discovery” means uncovering business impact, quantifying it and confirming it back to the buyer, that definition holds in Milan and in Helsinki. The rubric stays global too: the same anchors, the same levels, the same evidence requirements. If Spain is scored on a five-level rubric and Germany on a three-level one, your cross-country dashboard is decoration.
What must be local is everything that makes the practice feel real. Scenarios, personas, objection sets, buying committee structures, regulatory scripts, tone of the counterpart. Take the same discovery call for a mid-market software deal:
- Germany: the buyer wants specification depth before value. Expect early questions on data processing, subcontractors and where the servers sit. The rep who leads with ROI storytelling loses credibility in minute two.
- France: more hierarchy in the room. The technical evaluator may be enthusiastic and completely without signing power. The competency being tested is stakeholder mapping under polite ambiguity.
- Italy: relationship first, high tolerance for a longer opening, but a very fast pivot to price and payment terms. The objection “manda un preventivo” arrives earlier than any Anglo playbook expects.
- Spain: consensus-driven, several people in the call, decision timing genuinely elastic around August. Testing “confirming next steps” here is a different skill.
- Poland: strong price scrutiny and direct comparison to local providers. Reps need to handle “we can get something similar cheaper” without discounting reflexively.
- Nordics: low-context, allergic to overselling, short calls. Enthusiasm reads as pressure. The competency at stake is restraint and precision.
Same rubric. Six genuinely different conversations.
The translation trap
Here is the failure pattern I see most often in multilingual training rollout projects. A central team builds twenty excellent scenarios in English, sends the transcripts to a translation vendor, gets them back in eleven languages, and considers localisation done.
Then adoption dies within six weeks.
The reason is that a scenario is not text. It is a set of behavioural assumptions: how quickly the buyer objects, how directly they say no, whether silence means disagreement or thinking, whether the counterpart will interrupt. A perfectly translated German objection delivered with Italian conversational rhythm is uncanny. Learners notice instantly and stop trusting the exercise.
A translated scenario tests language comprehension. A localised scenario tests competence. Only one of those is worth your budget.
The practical fix: translate the rubric, rebuild the scenarios. Give each country the competency, the target behaviour and the evidence the assessment looks for, then let local enablement write the persona, the objections and the wording. In our experience with localisation training scenarios, the cost difference is smaller than people fear, because rewriting three objections is faster than fixing eleven awkward translations.
Works councils: talk before you build
If you operate in Germany, Austria, the Netherlands or France, the works council conversation is not a compliance formality you handle at go-live. Under the German Betriebsverfassungsgesetz, systems capable of monitoring employee performance and behaviour fall under co-determination. That is not a grey area, and discovering it in week three of deployment is how a works council ai training project becomes a twelve-month standoff.
What actually de-escalates the conversation:
Disclose the mechanics fully. Which competencies are assessed, what the rubric anchors say, how a score is produced, how long recordings are kept, who can see individual results, and what happens if the assessment is wrong. Being precise about where automated scoring ends and a human reviewer signs off removes most of the fear in the room, because the objection is rarely “AI” in the abstract and almost always “who decides, and can it be challenged”. Vagueness reads as concealment.
Then be explicit about what you do not score. Do not score accent, fluency, speaking speed, filler words, emotional tone or anything that correlates with language proficiency rather than competence. Say that in writing. The fastest way to lose a works council is to score how someone sounds rather than what they do.
Position the practice environment as formative, not as an input to performance reviews or pay. If individual scores feed appraisal, expect a much harder negotiation, and honestly, expect to lose the trust of the learners too. Aggregated, anonymised data for programme design is a far easier ask and gives HQ what it actually needs.
GDPR, recordings and where data lives
Voice and video practice generates personal data, and depending on how you configure it, potentially biometric data, which sits in the special category under Article 9 GDPR. That changes your legal basis, your DPIA obligations and your retention posture.
Four decisions to make before the pilot, not after:
- Legal basis. Consent is fragile in an employment context because of the power imbalance. Legitimate interest with a documented balancing test is usually more defensible, but get your DPO to own the call.
- Residency. Know which region processes and stores recordings, and whether any subprocessor sits outside the EEA. German and French entities will ask. Have the answer in the vendor contract, not in an email.
- Retention. Default to short. Ninety days for raw recordings and longer for anonymised scores covers most audit needs without building a liability archive.
- Access. Country L&D sees their country. Managers see aggregates. HQ sees anonymised comparison. Nobody browses recordings casually.
If your programme also carries regulated content, financial suitability conversations under MiFID II, customer due diligence and anti-money-laundering interviews or promotional compliance in pharma, the audit trail requirement pulls in the opposite direction: you need durable evidence that specific people practised specific behaviours. Reconcile those two pressures explicitly rather than hoping nobody notices.
A rollout model that survives contact with twelve countries
Wave one is a pilot country. Pick somewhere with a strong local L&D partner, a manageable regulatory profile and enough volume to produce signal. Not your biggest market. You are testing the model, not proving the business case.
Wave two is a template country, and this is the step most programmes skip. Choose the hardest environment you have, usually Germany or France, with works council and strict data expectations. If the design survives there, it survives everywhere. Everything you produce in the template country becomes the reference kit: rubric translations, DPIA, works council briefing pack, scenario authoring guide.
Wave three onward is deployment in waves of three or four countries, each with a named local owner. In markets where most of the population sits in contact centres, the binding constraint is not appetite but the roster, so plan for short practice blocks that fit around live queues instead of pulling agents off the floor for a full training day.
Governance of scenario creation deserves its own decision. Full central control produces scenarios nobody believes. Full local freedom produces twelve incomparable programmes. The workable middle: HQ owns the competency model, the rubric and the assessment logic. Local owners can create and edit scenarios freely within a certified template, but cannot change scoring criteria. A quarterly review samples local scenarios for rubric alignment.
Metrics that compare countries fairly
The moment you put twelve countries on one dashboard, you create a ranking, and rankings punish whoever practises in their second language.
Compare improvement, not absolute level. Delta from baseline within a country tells you whether the programme works. Cross-country absolute scores tell you mostly about language and market difficulty. Agreeing the baseline, the comparison window and the business metric before wave one is what separates a programme that renews from one that gets audited by finance, and a measurement framework that connects practice to business outcomes is far easier to agree up front than to reconstruct in month nine.
Track competency-level breakdowns rather than a single composite. “Objection handling improved 22 points in Poland while discovery stayed flat” is actionable. A country score of 3.4 is not.
Watch practice volume and completion as leading indicators, and if one country’s volume collapses, assume the scenarios feel fake before you assume the people are disengaged. Before reaching for leaderboards to fix it, be clear about which engagement mechanics actually sustain practice and which ones just inflate activity: a cross-country ranking board is exactly the mechanic that penalises second-language teams. Then check the rubric for proficiency bias: if fluency correlates strongly with score across your whole population, your rubric is measuring the wrong thing.
A global l&d programme is not one programme running twelve times. It is one measurement system running against twelve different realities. Get the rubric global, the fiction local, the works councils early and the metrics fair, and multi-country training deployment stops being a governance headache.
Want to see how competency-based assessment stays consistent across languages while scenarios stay local? Book a demo.
Stay in the loop
Get the latest insights on corporate training delivered to your inbox.