Beyond Sales: Using AI Roleplay to Train Managers, Support, Collections and Back-Office Teams
AI roleplay isn't just for sales. The costliest conversations happen in management, support, collections, HR and procurement, see the scenarios and metrics for each department.
Roleplays Team
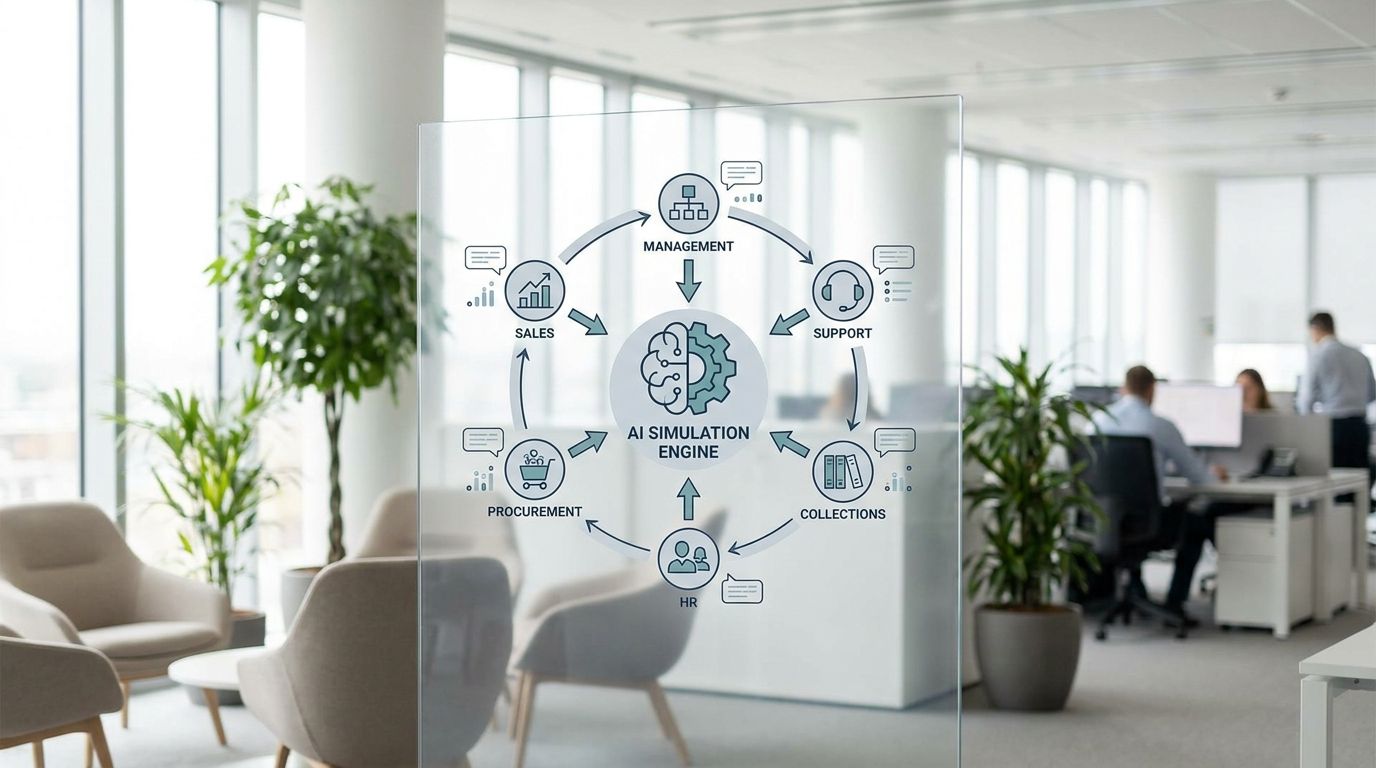
TL;DR Almost every AI roleplay vendor sells to sales enablement, which trains buyers to think the category stops at cold calls. The highest-cost conversations in a 1,000+ employee company happen elsewhere: a manager delivering a performance review, an agent de-escalating a churn-risk customer, a collector negotiating a promise-to-pay, an HR lead running an investigation. If your platform can only score discovery and objection handling, you bought a sales tool, not an L&D capability.
The blind spot: the category sold itself short
Look at the top ten search results for “AI roleplay training” and count how many position around sales. Cold call simulators. Objection handling bots. Pitch scorecards. The messaging is so uniform that most heads of L&D file the whole category under “enablement” and move on.
That is a category positioning problem, not a technology limit. The underlying capability, which we unpack in detail in what AI roleplay for corporate training actually is and where it pays off, is simple: simulate a difficult conversation with a realistic counterpart, then evaluate the behaviors against a rubric. Nothing in that sentence says “prospect.”
The expensive conversations in your company are rarely the sales ones. A botched cold call costs you a meeting. A botched termination conversation costs you a wrongful dismissal claim. A botched collections call costs you a regulatory complaint. Yet the second and third categories almost never get deliberate practice, because the tooling was marketed to a different buyer.
Department by department: the conversation, the scenario, the metric
Here is the practical breakdown. For each function, the conversation that costs money when it goes wrong, a scenario you could build this quarter, and the number it should move.
| Department | High-cost conversation | Sample scenario | Metric it moves |
|---|---|---|---|
| People managers | Performance and corrective feedback | Tell a tenured, defensive high performer their behavior is failing the team | Regretted attrition, manager effectiveness score |
| Customer support | De-escalation and expectation setting | Angry customer, third contact, no resolution, threatening to cancel | First-contact resolution, CSAT, repeat contact rate |
| Collections | Promise-to-pay negotiation | Debtor in genuine hardship, agent must stay inside FDCPA-style constraints | Promise-to-pay rate, kept-promise rate, complaint volume |
| HR / ER | Investigations and offer negotiation | Interview a witness in a harassment complaint without leading or contaminating | Time to close case, litigation exposure |
| Field service | Discovery, upsell and safety pushback | Technician spots an unsafe install; customer refuses the fix and wants a discount | Attach rate, safety incident rate, callback rate |
| Procurement / back office | Supplier negotiation and internal escalation | Supplier pushes a 12% increase citing input costs, three weeks before contract end | Cost avoidance, cycle time |
Managers: the conversation everyone avoids
Ask any CHRO where the leadership gap sits and you will hear the same thing. Managers can run a one-on-one. They cannot run the one-on-one where they tell someone the performance is not there. So they delay it, soften it into ambiguity, and the employee is genuinely surprised at the review.
A manager who has rehearsed that conversation eight times against a persona that pushes back, cries, or goes silent behaves differently than a manager who watched a video about radical candor.
Support: de-escalation is a skill, not a script
Contact centers spend their onboarding budget on systems training and product knowledge, then send new agents to learn de-escalation on live customers. The customer pays the tuition. The usual objection is capacity, and it is a fair one, though there are ways to build deliberate practice into the shift itself without pulling agents off the floor.
If your new agent’s first genuinely hostile call is a real one, you did not train them. You outsourced the risk to your customer base.
Support roleplay is where multimodality matters most. Voice practice for phone queues, chat practice for chat queues. Scoring an agent’s typed empathy on a voice rubric produces noise. The same speech signals that voice analytics use to lift CSAT on live calls are what make a voice rubric meaningful in practice: pace, interruption, recovery after the customer escalates.
Collections: the highest regulatory density per minute
Collections is a compliance conversation wearing a sales conversation’s clothes. In the US, the Consumer Financial Protection Bureau’s Regulation F sets specific rules on contact frequency, disclosure and third-party communication (you can read the rule text on consumerfinance.gov). One improvised sentence about wage garnishment can create a documented violation.
Collections training is exactly the use case where practice plus auditable evidence beats a policy quiz. It is the same logic that makes simulation work for KYC and AML training in banks, where the regulator cares about what the employee actually did, not what the course said. You want the transcript, the score, the rubric criterion that failed, and the date, retrievable when an examiner asks.
HR, field service and procurement
HR investigations fail on question design: leading questions, premature conclusions, poor handling of a witness who asks “will he know I said this?” That is rehearsable. Offer negotiation is rehearsable too, and it directly touches offer acceptance rate.
Field service technicians are your largest untrained customer-facing population in most industrial companies. They perform hundreds of thousands of conversations a year with no enablement function watching. Procurement, meanwhile, negotiates real money against professional negotiators who do this all day.
Why a single-vertical platform cannot stretch to cover this
Vendors will tell you their sales tool “works for any scenario.” Sometimes true at the demo level, almost never true at the program level. Four things break.
Scenario engine. A sales scenario has a linear structure: opening, discovery, objection, close. An HR investigation branches on what the witness discloses. A collections call branches on the debtor’s stated hardship and the agent’s obligation to stop or continue. If the engine only supports a funnel, you cannot model the branch.
Persona library. Sales personas are buyer archetypes: the skeptic, the budget holder, the champion. You need a defensive employee, a hostile customer, a supplier’s procurement lead, a witness who is afraid of retaliation. Different emotional registers, different escalation logic, different silence behavior.
Rubric flexibility. This is the real dividing line. A sales rubric scores talk ratio, question quality, objection handling. A collections rubric scores mandatory disclosures, prohibited statements, tone under pressure. A manager rubric scores specificity of evidence, ownership language, clarity of consequence. Deciding which of those criteria a model can score reliably and which still need a human reviewer is a design decision in itself, and we mapped it out in AI evaluation versus human evaluation in L&D. If you cannot author your own competency framework and reuse criteria across departments, you will end up with five disconnected tools and no comparable data.
Localization. For a US and Canadian enterprise this is not just Spanish and French. It is bilingual Canadian compliance requirements, provincial employment nuance, and accent and register variation in the persona voice. A collections script that is compliant in Ohio is not automatically compliant in Quebec.
The evaluation checklist: prove it, do not claim it
Take this into the vendor call. Ask for a live build, not a slide.
- Build a scenario I name, on the call. Give them a manager performance conversation. Time it. If it takes their professional services team two weeks, cross-department rollout is unaffordable.
- Show me a non-sales rubric. Ask to see an existing collections or HR competency framework, with criteria and scoring anchors, not a generic “communication” score.
- Can I reuse a competency across departments? “Handles emotional escalation” should be one criterion measured in support, collections and management, with comparable data.
- Show me the audit trail. Who practiced, when, what score, what evidence, exportable, retention configurable.
- Show me French Canadian. Not a translated prompt. A persona that behaves natively.
- Show me three modalities on the same competency. Voice, video and chat, scored against the same framework.
- Who is the reference customer outside sales? If every logo is enablement, you are their experiment.
Sequence the rollout so department one funds department two
Do not launch six functions at once. Pick the department where the failure has the clearest dollar value and the shortest measurement window. In most enterprises that is contact center or collections: high volume, existing quality data, weekly metrics.
Run it for one quarter, instrument it properly (baseline first, or you will have no story), then use the delta to fund the manager program, which pays back on attrition over a longer horizon and needs the credibility of an earlier win.
Practically: quarter one, one department, three scenarios, one rubric. Quarter two, extend the same rubric library sideways. Quarter three, add the long-payback populations.
Where roleplay is the wrong tool
Honest caveat, because you will find this out anyway. Roleplay is a behavior tool, not a knowledge tool. If the gap is “the team does not know the new pricing tiers” or “nobody can find the credit memo screen,” a simulation is an expensive way to teach a fact. Use a knowledge check, a job aid, or systems training in the actual system.
Roleplay earns its cost when the failure is behavioral under pressure: the person knows the right answer and still does the wrong thing when the counterpart pushes back. That is most of your expensive conversations, but it is not all of your training needs. Anyone who tells you otherwise is selling.
FAQ
Is AI roleplay training only for sales teams? No. The category was marketed to sales enablement, but the same simulation and rubric mechanics apply to manager training simulation, customer service roleplay training, collections, HR investigations, field service and procurement.
What metric should we track for non-sales roleplay? Match the metric to the function: first-contact resolution and CSAT for support, promise-to-pay and complaint rate for collections, regretted attrition for managers, cost avoidance for procurement. Baseline before launch.
Can one platform really serve all departments? Only if the rubric layer is author-editable and reusable across functions. Test that specifically before signing.
Where should we start? The department with high conversation volume, existing quality data and a short measurement window. Usually contact center or collections.
Want to see a non-sales scenario built against your own competency framework? Book a walkthrough at /demo/ and bring the hardest conversation your managers avoid.
Stay in the loop
Get the latest insights on corporate training delivered to your inbox.